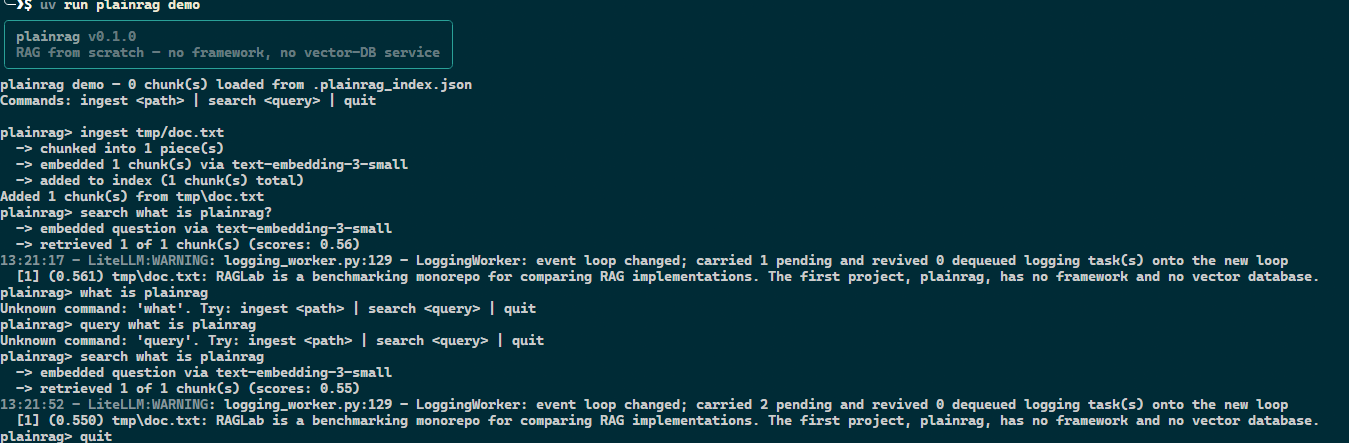
The first project in a benchmarking monorepo where I build the same RAG problem more than once, each project taking a different set of tradeoffs so those tradeoffs stay visible instead of hidden behind a library’s defaults. This one is the baseline: no RAG framework, no vector-database service — just a flat NumPy index with brute-force cosine similarity, word-window chunking, and prompt assembly, all provider-agnostic via litellm. A CLI (ingest / ask / demo) ingests a text file and answers questions grounded in it, narrating each pipeline step — chunk, embed, retrieve, generate — as it happens. See the full writeup for the architecture and design tradeoffs.
Citation
For attribution, please cite this work as:
Bakr, Mohamed. 2026. “RAGLab: RAG From Scratch.” September
14. https://mohdbakr.com/projects/rag-from-scratch/.